
Introduction
Similarity-based RAG based on Vector-DB has shown big limitations in recent AI applications. Reasoning-based or agentic retrieval has become important in current developments. PageIndex Chat is an AI assistant that allows you to chat with multiple super-long documents without worrying about limited context or context rot problems. It is based on PageIndex, a vectorless reasoning-based RAG framework which gives more transparent and reliable results like a human expert.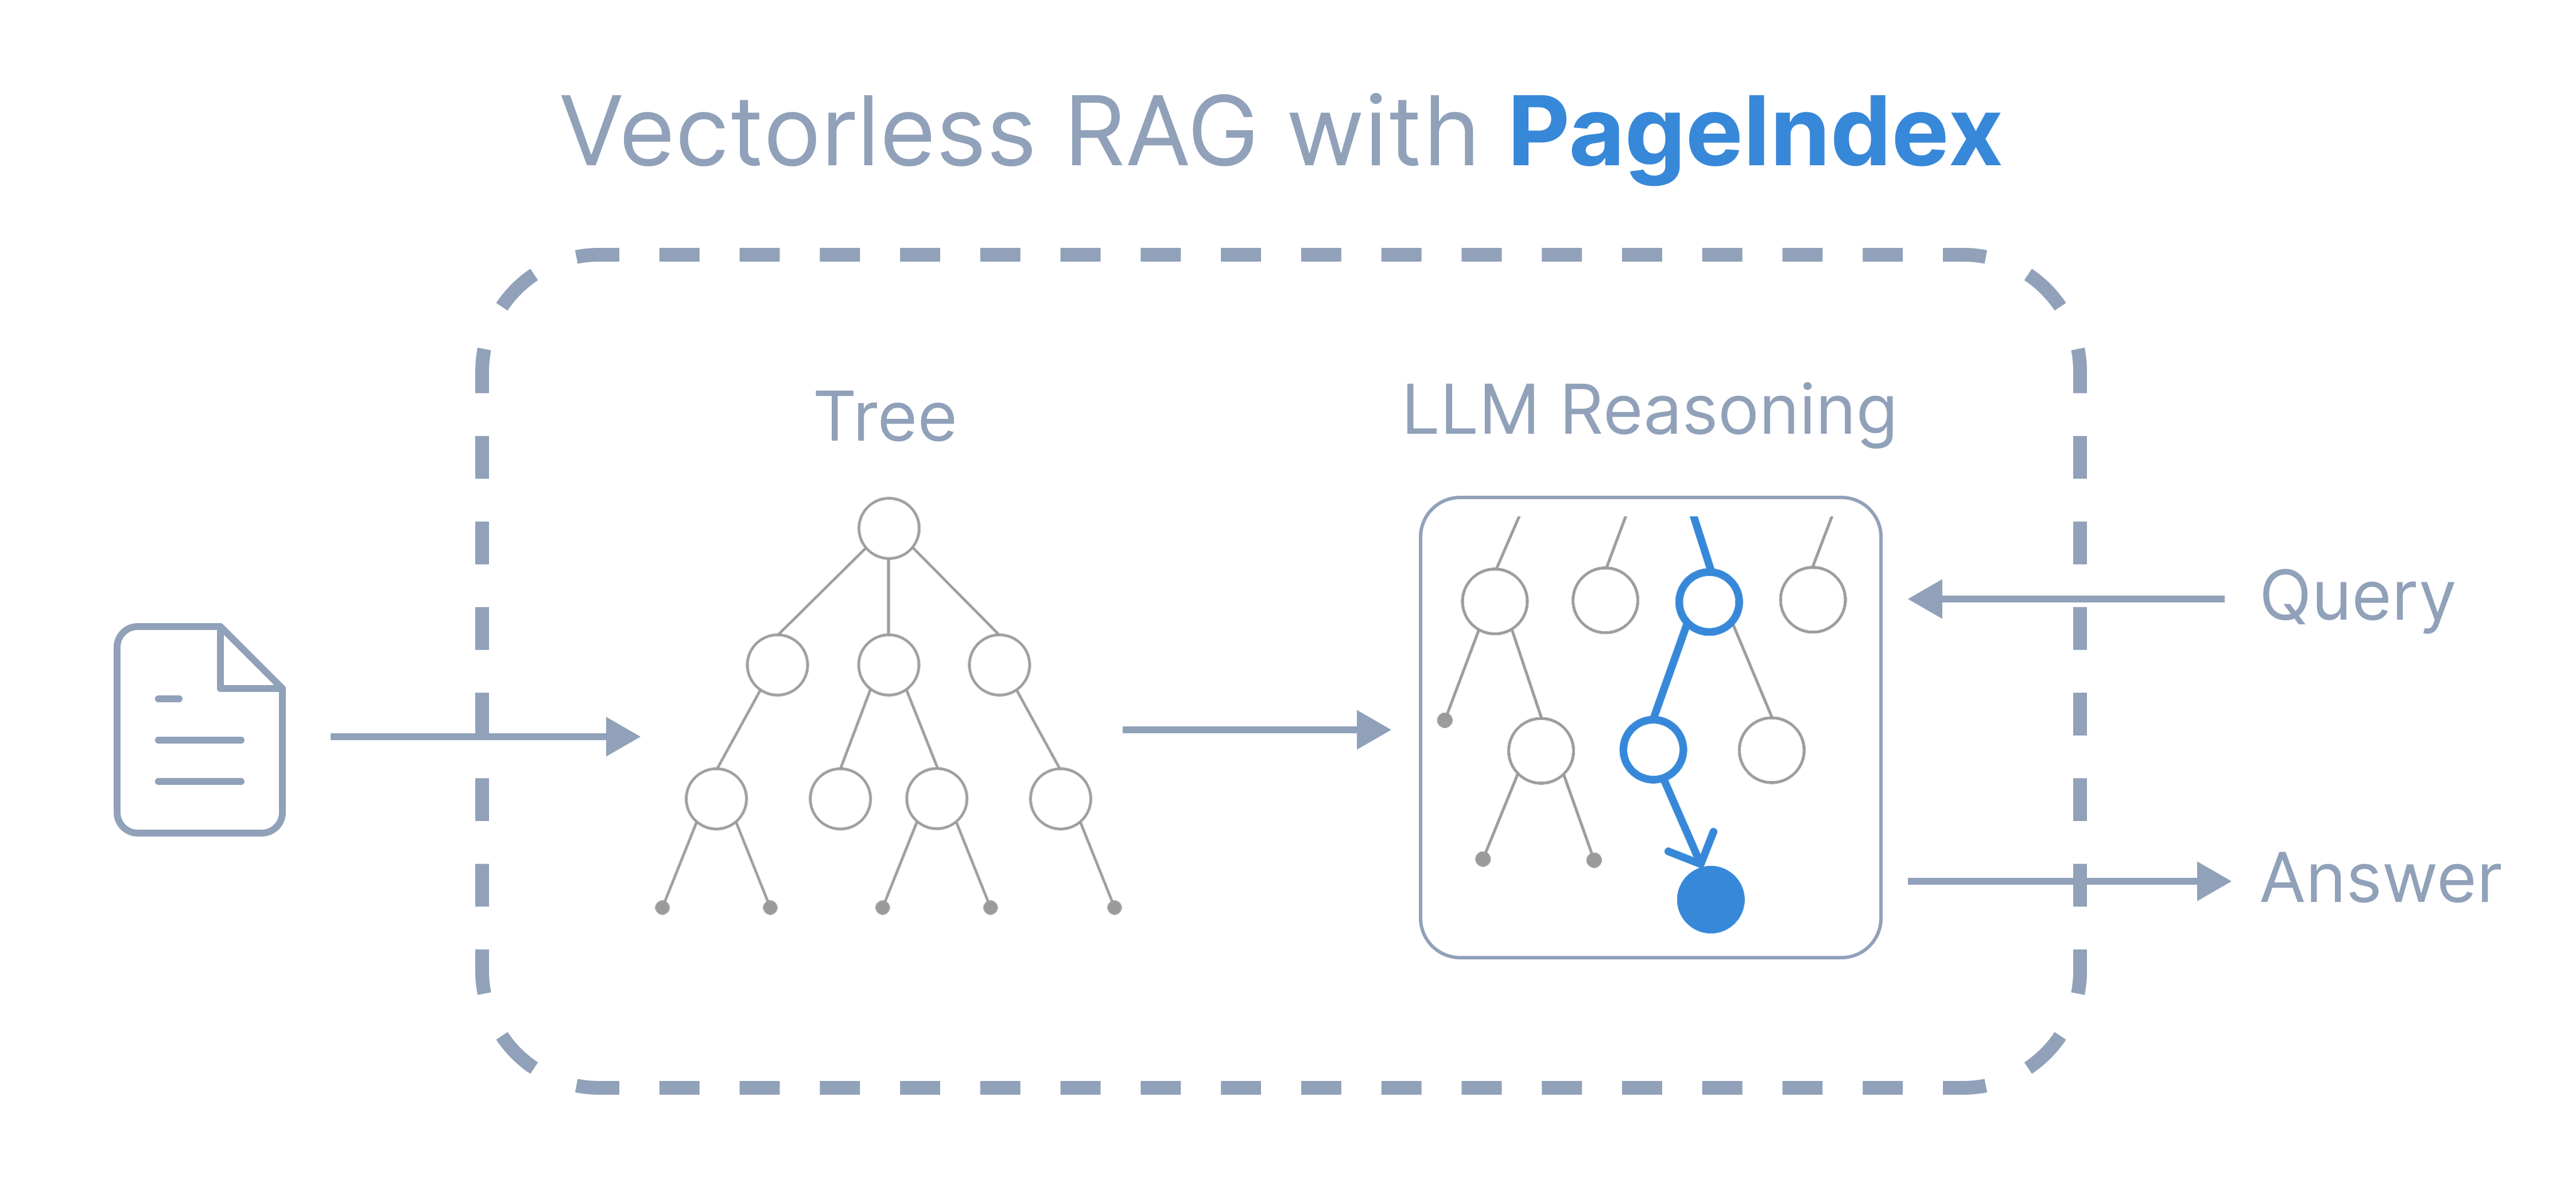 You can now access PageIndex Chat with API or SDK.
What You’ll Learn
This cookbook demonstrates a simple, minimal example of doing document analysis with PageIndex Chat API. You will learn how to:- Upload documents to PageIndex
- Check document processing status
- Ask questions about documents using the Chat API
- Work with streaming responses
This example uses NVIDIA’s recently released 10-Q report to demonstrate the capabilities.
Setup
1
Install PageIndex SDK
Install the PageIndex SDK:
2
Setup PageIndex Client
Initialize the client with your API key:
Upload a Document
Download and submit a document for processing:Check Processing Status
Verify that the document processing is complete:Processing time depends on document length. The status will be
'processing' while PageIndex generates the document tree structure, and 'completed' when ready.Ask Questions
Use the Chat API to ask questions about the document:Key Features
Long Document Support
Handle documents with hundreds of pages without context limitations
Transparent Reasoning
See which pages and sections the answer comes from
Streaming Responses
Get real-time streaming responses for better user experience
Multi-turn Conversations
Support for conversational context across multiple questions
Advanced Usage
Non-Streaming Mode
For simpler use cases, you can disable streaming:Multi-turn Conversations
Maintain conversation history for follow-up questions:What Makes PageIndex Different?
Unlike traditional RAG systems that rely on vector similarity search:1
Document Structure
PageIndex builds a hierarchical tree structure of your document, preserving natural sections and organization
2
Reasoning-Based Retrieval
Instead of vector similarity, PageIndex uses LLM reasoning to navigate the document tree and find relevant content
3
Transparent Results
You can see exactly which pages and sections were used to generate the answer, making it easy to verify and trace back to the source
4
No Context Limits
Handle super-long documents without worrying about context window limitations or context rot
Learn More
Try PageIndex Chat
Use the web interface to chat with your documents
API Reference
Explore the full API documentation
PageIndex MCP
Integrate PageIndex with Model Context Protocol
GitHub Repository
Check out open-source implementations
Next Steps
- Explore Vectorless RAG for custom implementations
- Try Vision-based RAG for OCR-free document processing
- Learn about Agentic Retrieval patterns